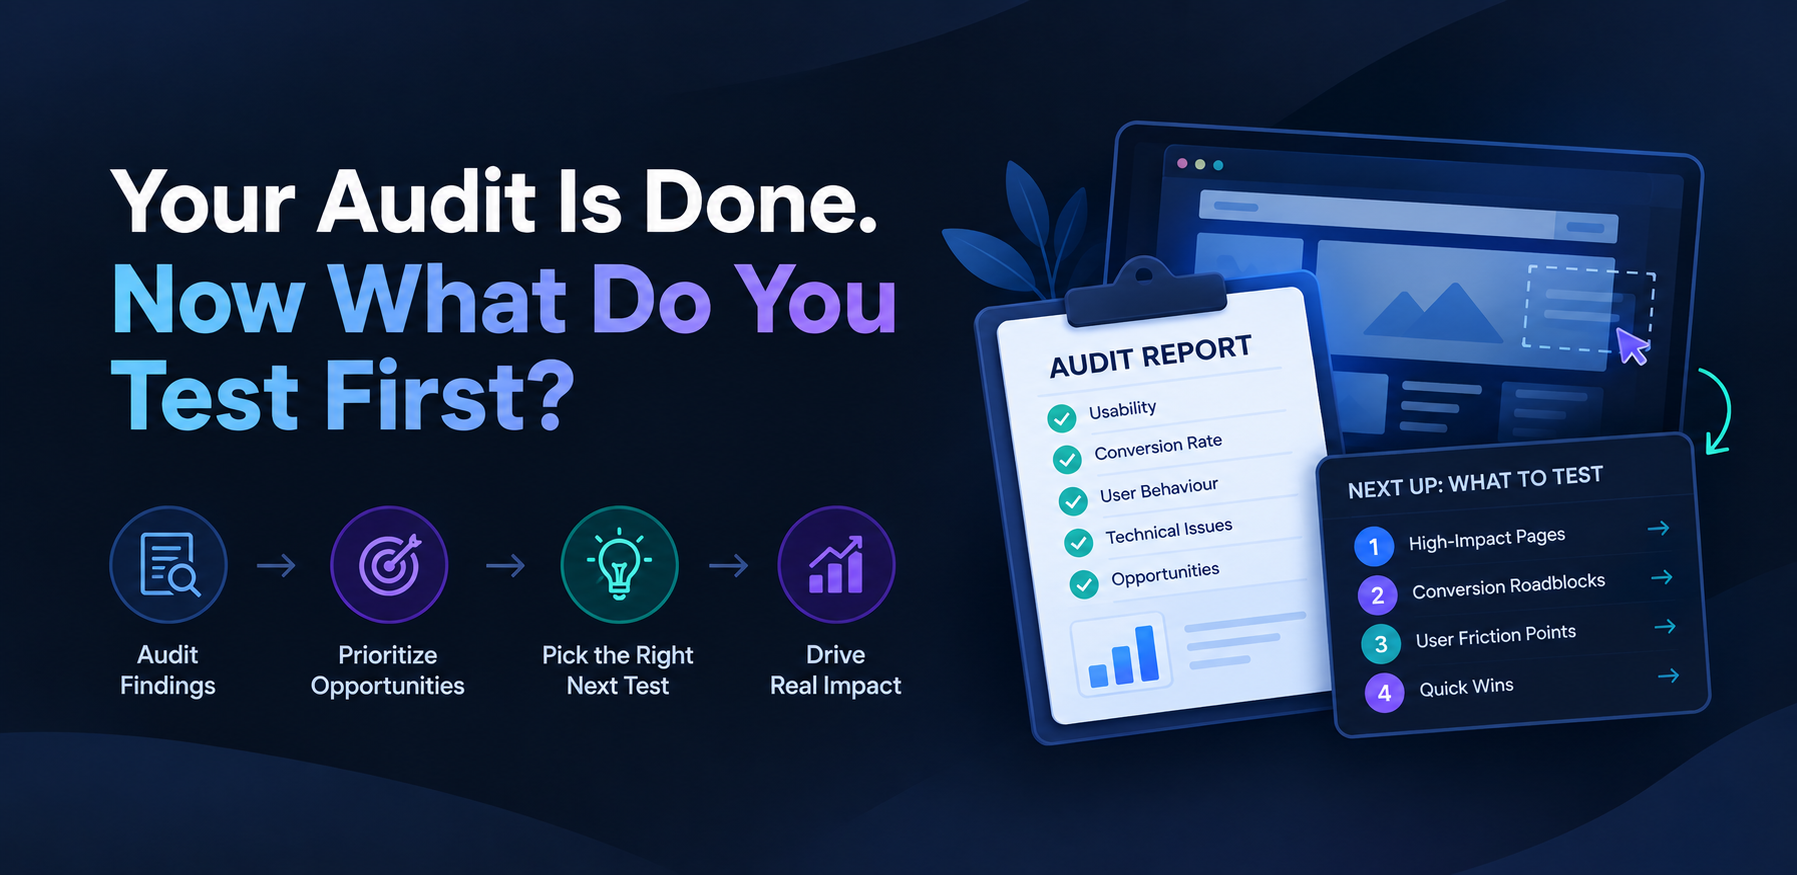
Your Audit Is Done. Now What Do You Test First?
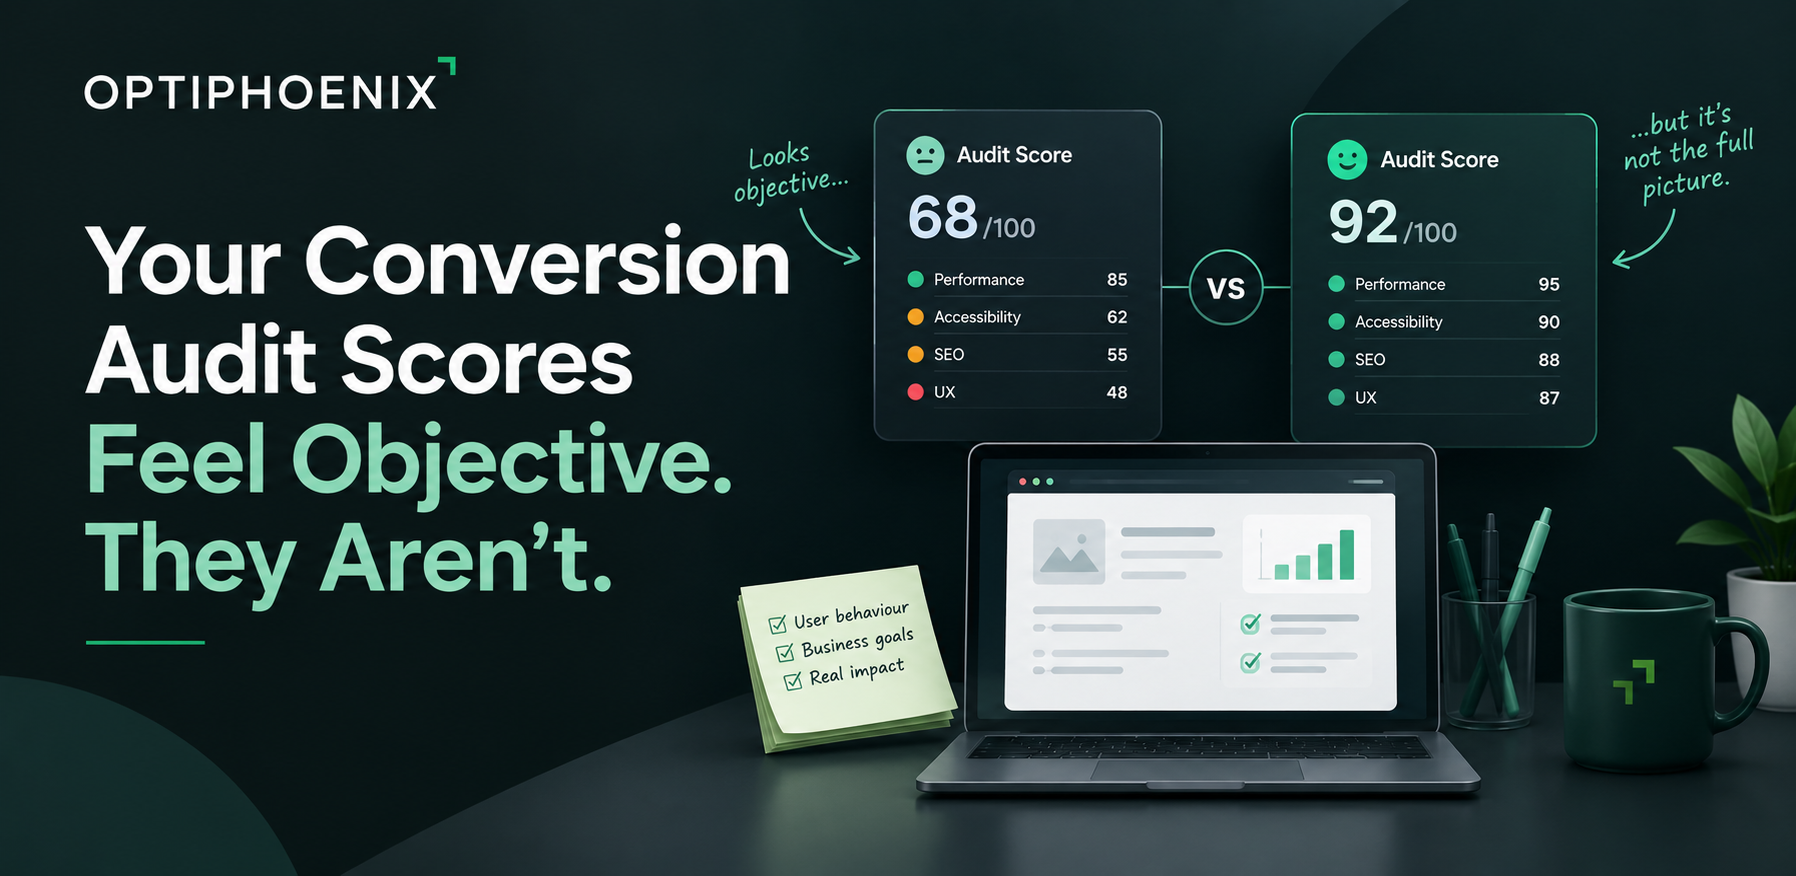
Every CRO audit guide eventually lands on the same approach: score each finding for Impact, Confidence, and Ease, usually from one to ten. Multiply the scores and start with whatever ends up at the top. ICE, PIE, whatever acronym you use, the idea is basically the same. And as a first pass, it’s useful.
The problem comes when those scores start looking like hard data. They aren’t. A 7 for impact and an 8 for confidence don’t suddenly make something measurable. They’re still estimates. Just estimates with numbers attached.
Nobody explains where the seven comes from. You look at a finding, you feel roughly confident it’ll work, and you write down a number that matches the feeling. That’s not a criticism of the person doing it. It’s just what scoring on instinct looks like, dressed up as a spreadsheet column.
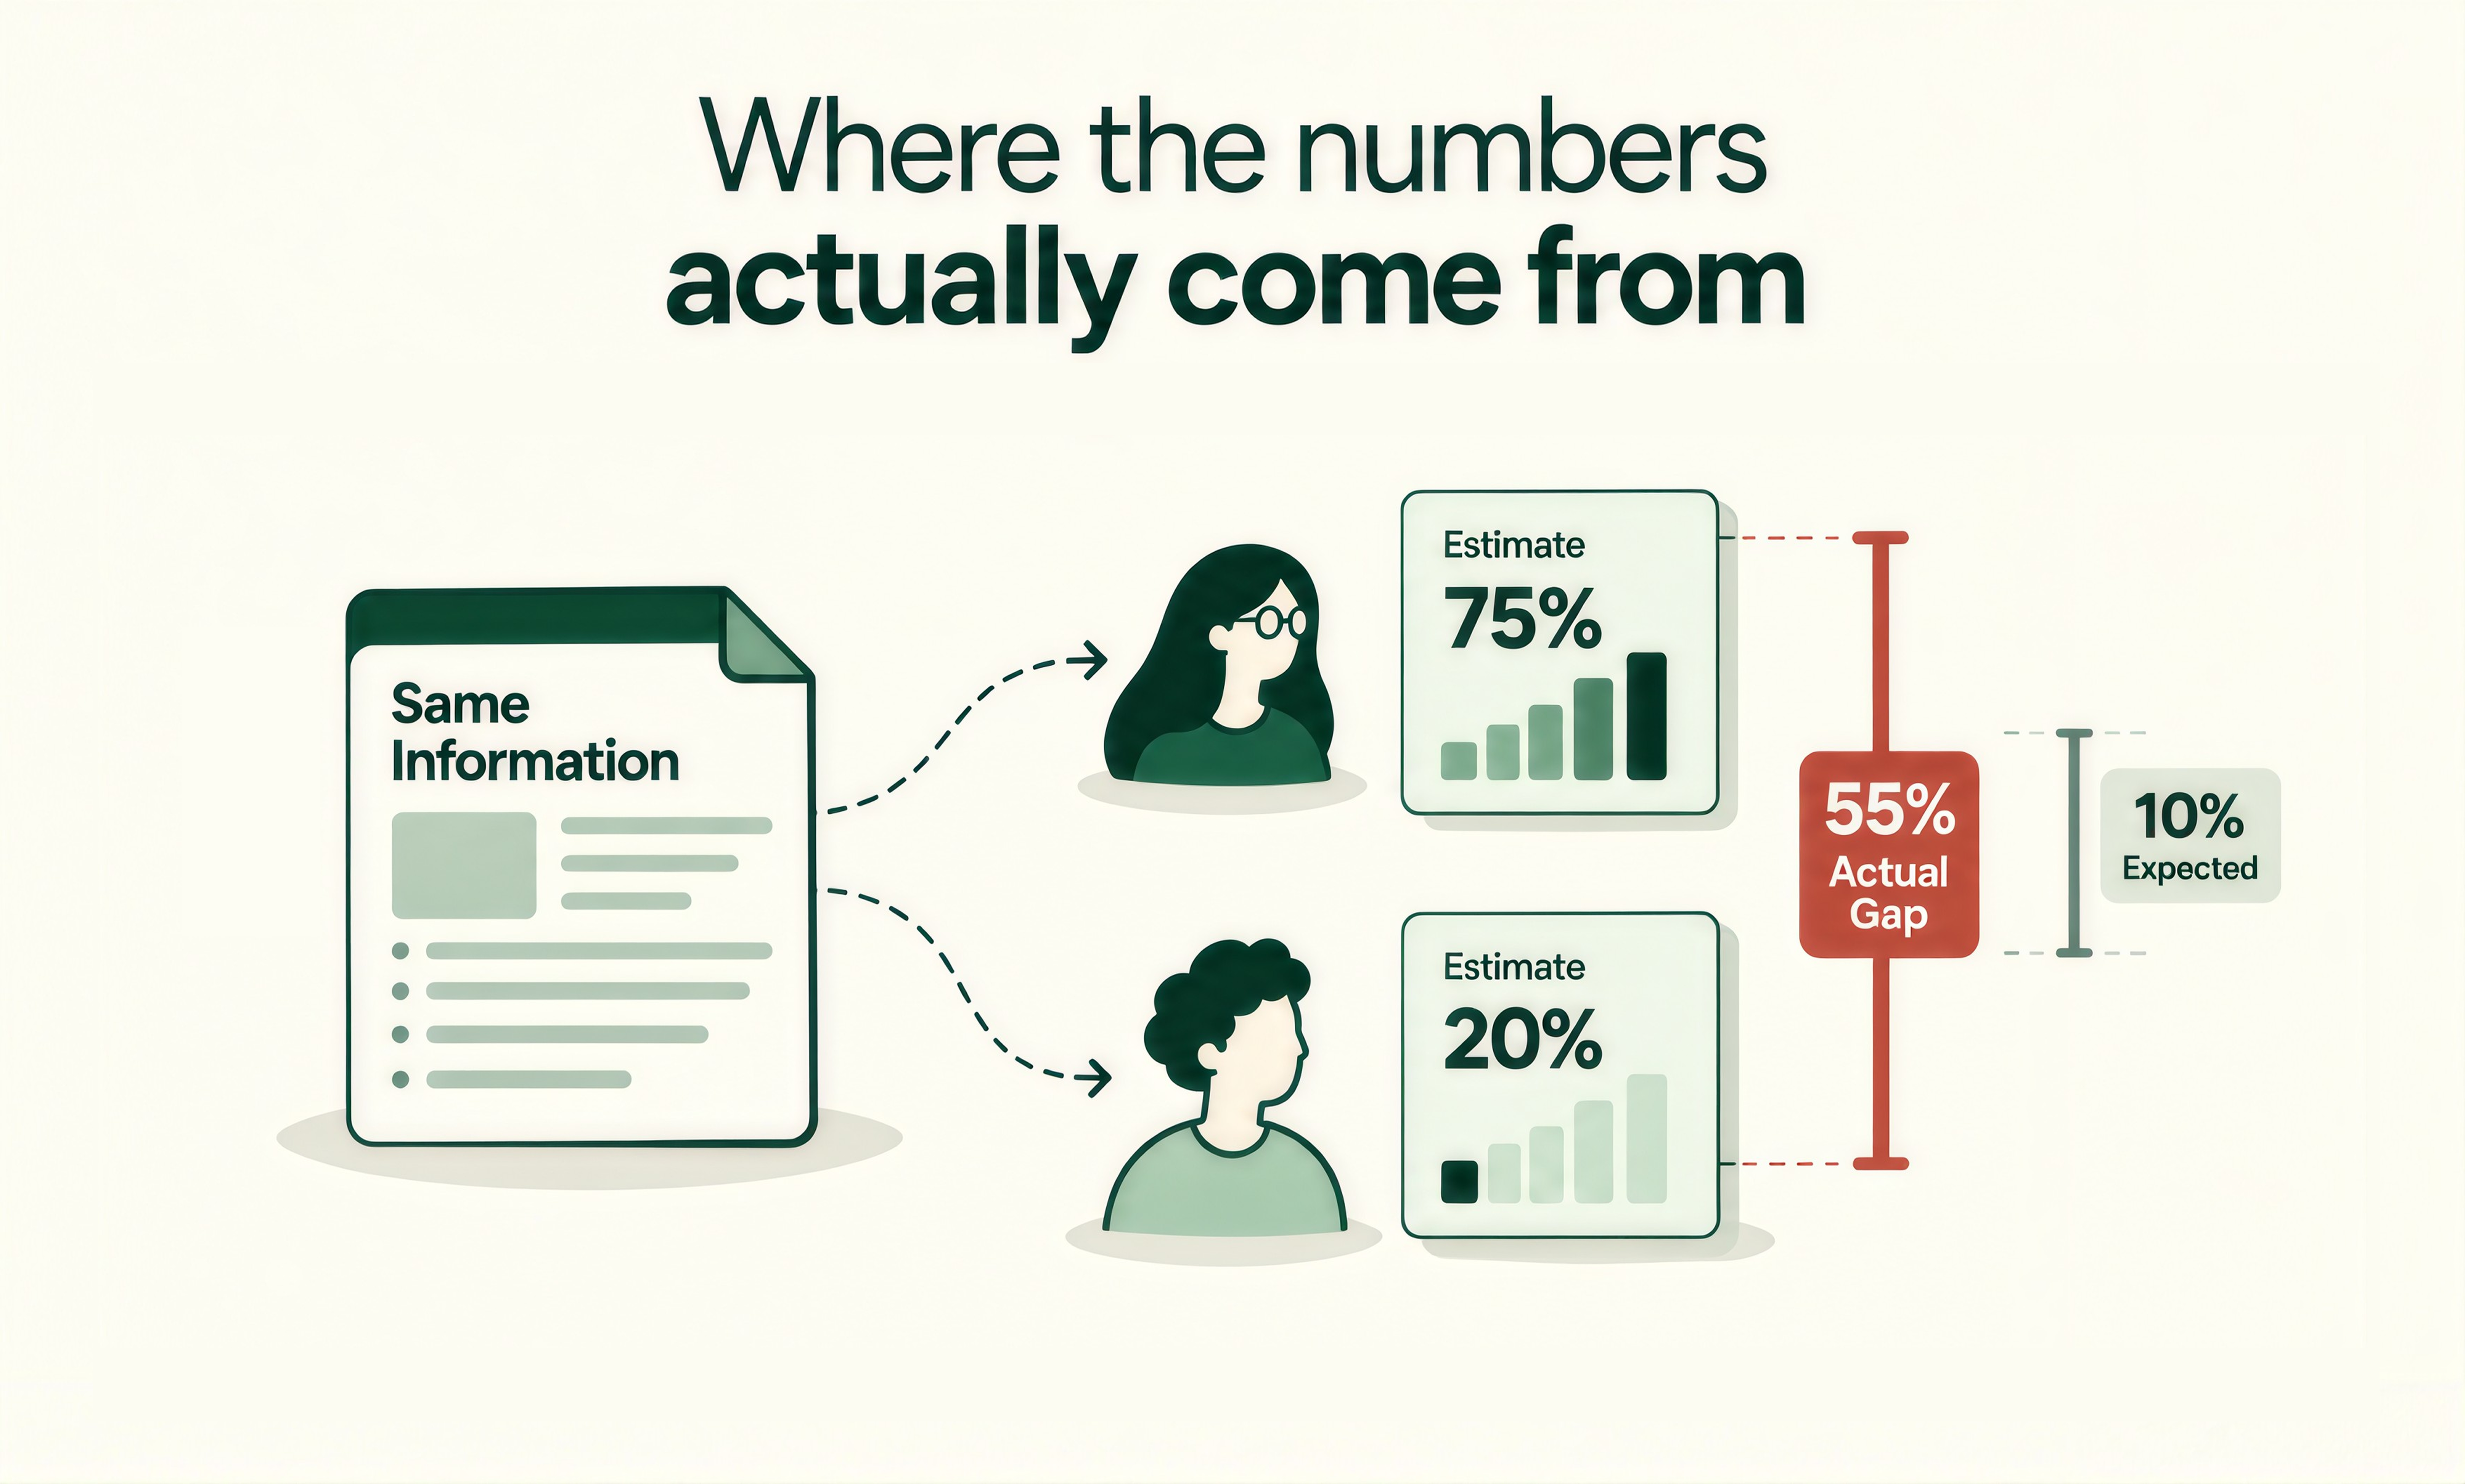
Daniel Kahneman spent years studying exactly this kind of judgment, and the results are worth sitting with. In one exercise, insurance underwriters each estimated the loss on the same case, working independently. The median difference between two underwriters looking at identical information came out to 55% of their average estimate. The executives who ran the exercise had guessed the gap would be closer to 10%. Multiplying three subjective numbers together doesn’t make the result more objective. It just means the guess now has more decimal places.

This part tends to surprise people more than it should. In another of Kahneman’s studies, judges reviewed randomly assigned, functionally identical asylum cases. Approval rates ranged from 5% to 88%, depending entirely on which judge got the file. Recruitment panels who watched the exact same candidate interviews still disagreed on who the best fit was about a quarter of the time.
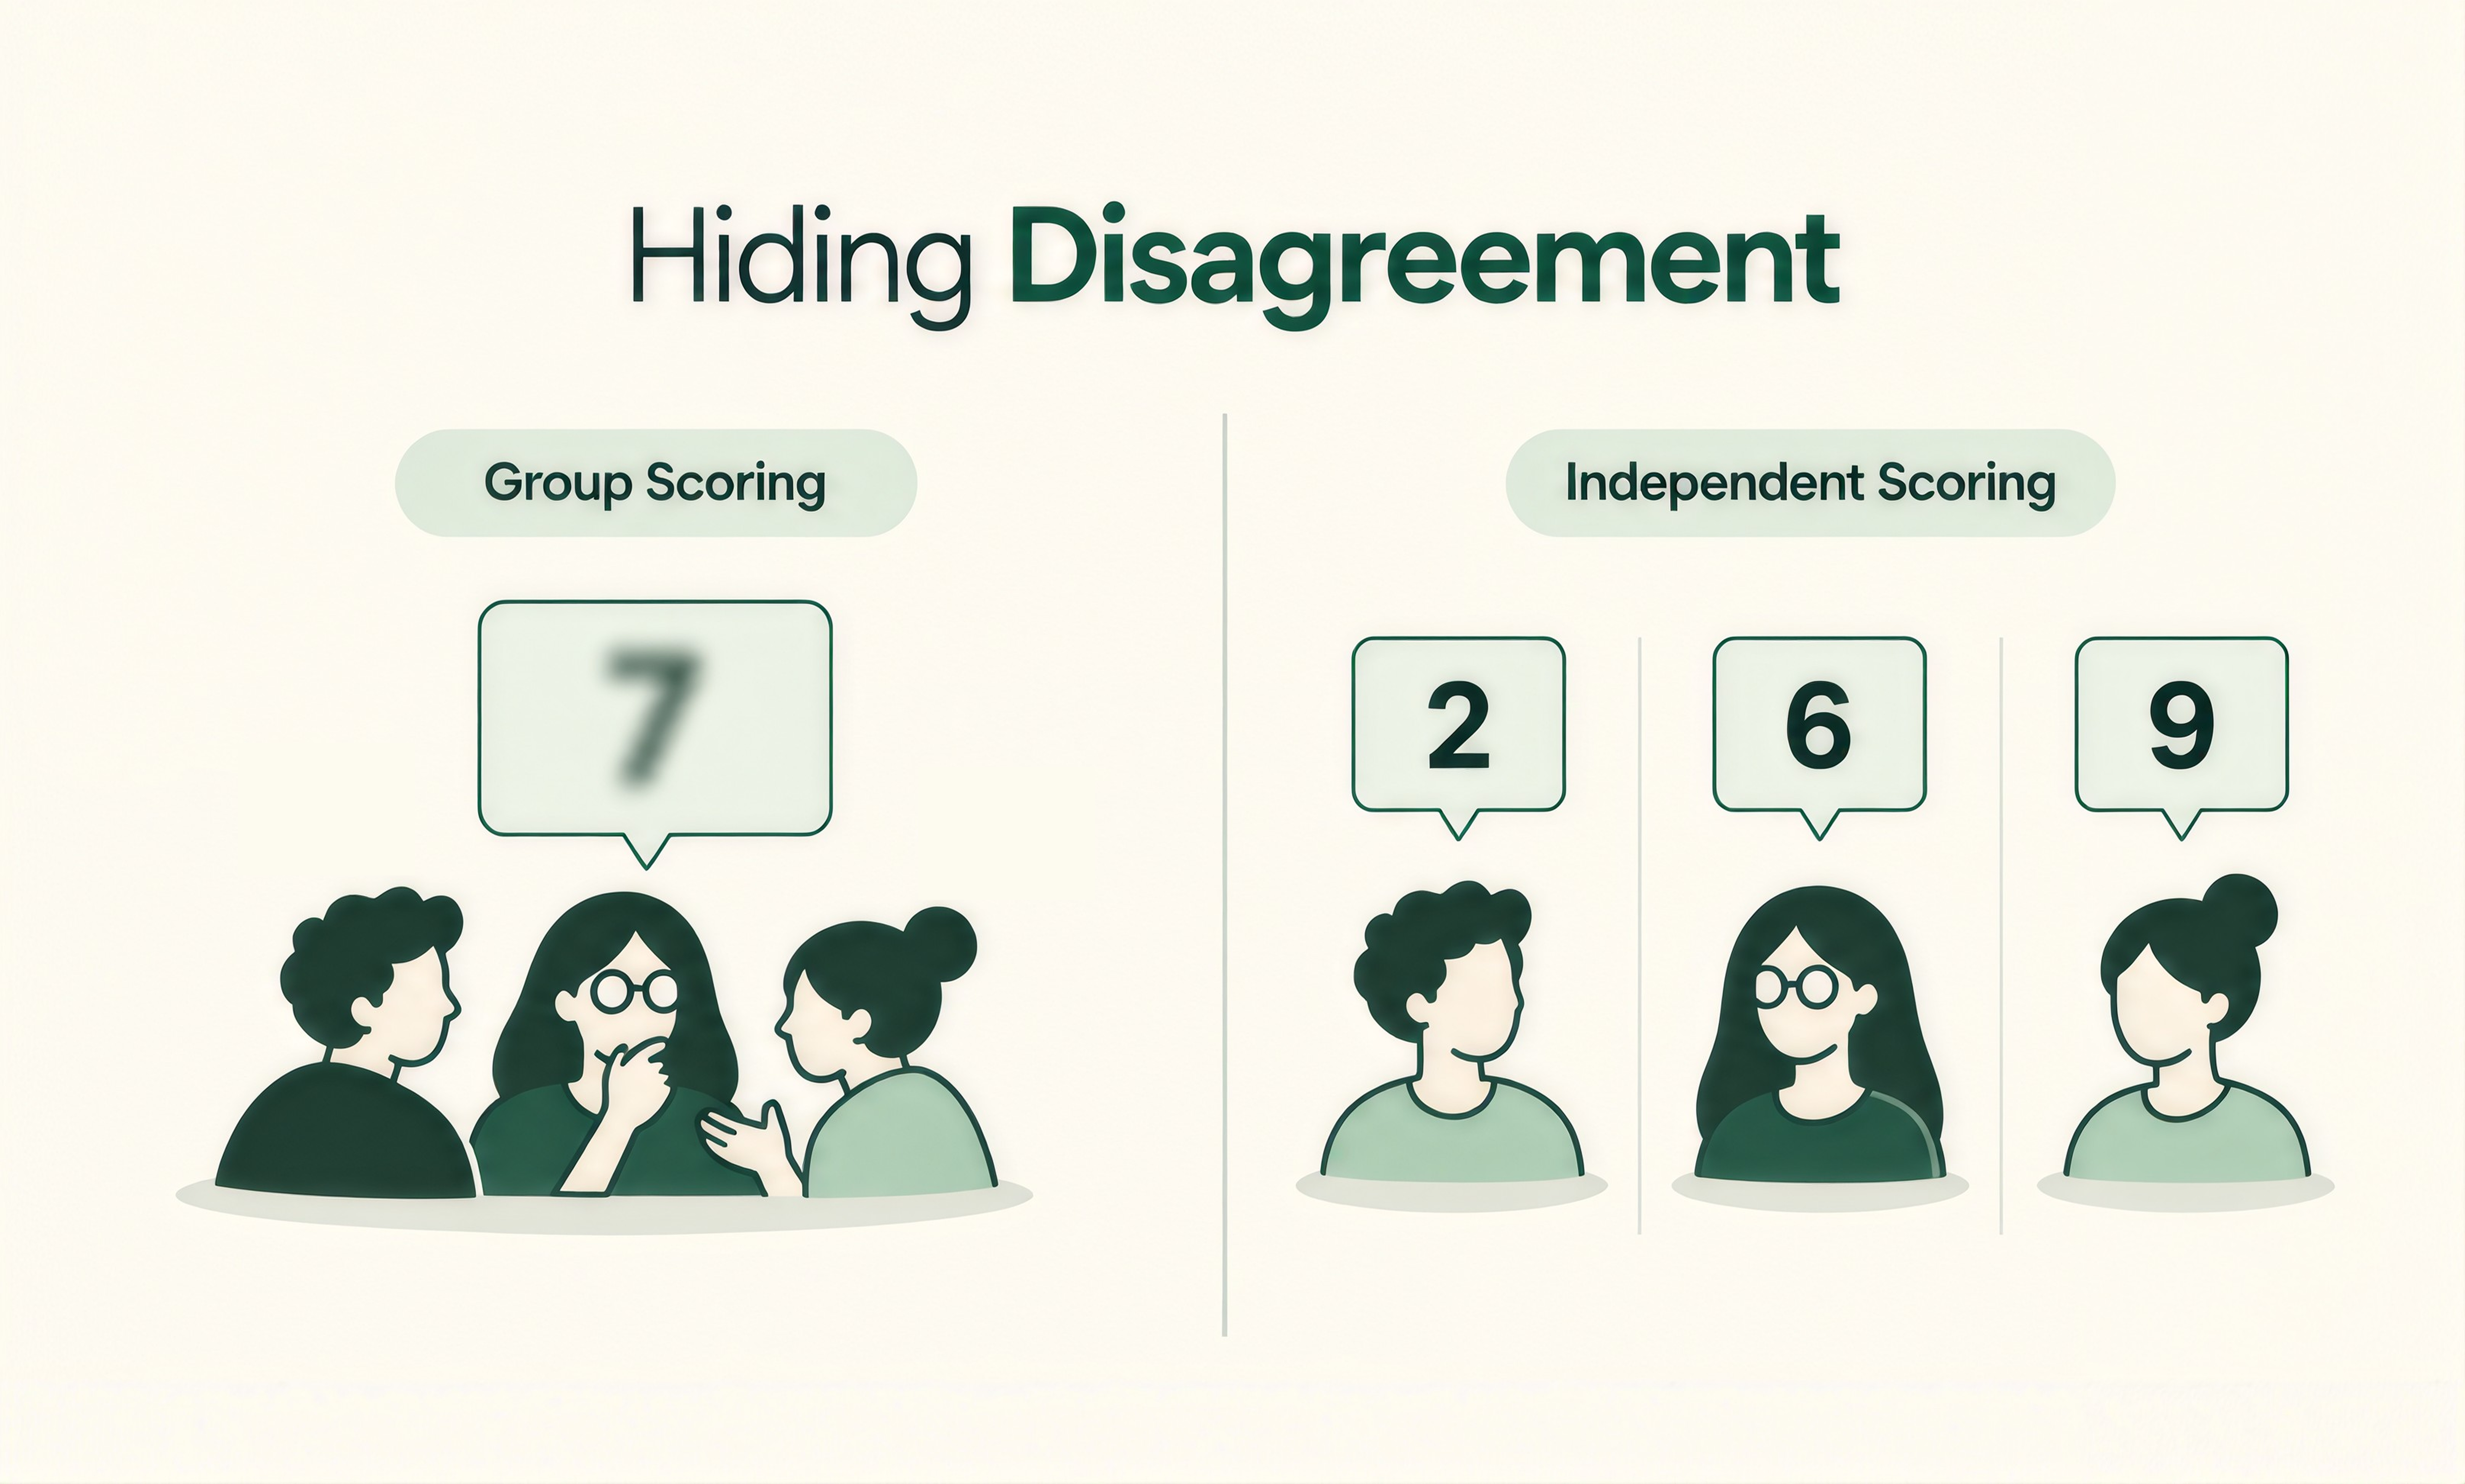
Nobody’s ICE or PIE framework checks for this. Two people on the same team can score the same audit finding and land on genuinely different numbers. That’s especially true on Confidence, the softest and most opinion-driven of the three inputs most frameworks use. If nobody ever tests for that gap, the framework just quietly absorbs whichever person happened to be doing the scoring that day.
Once a finding gets a number, that number tends to stay fixed forever. Nobody goes back three months later, after the test has actually shipped, and checks whether the Confidence: 8 they wrote down turned out to mean anything. The prediction and the outcome live in two different places and never meet.
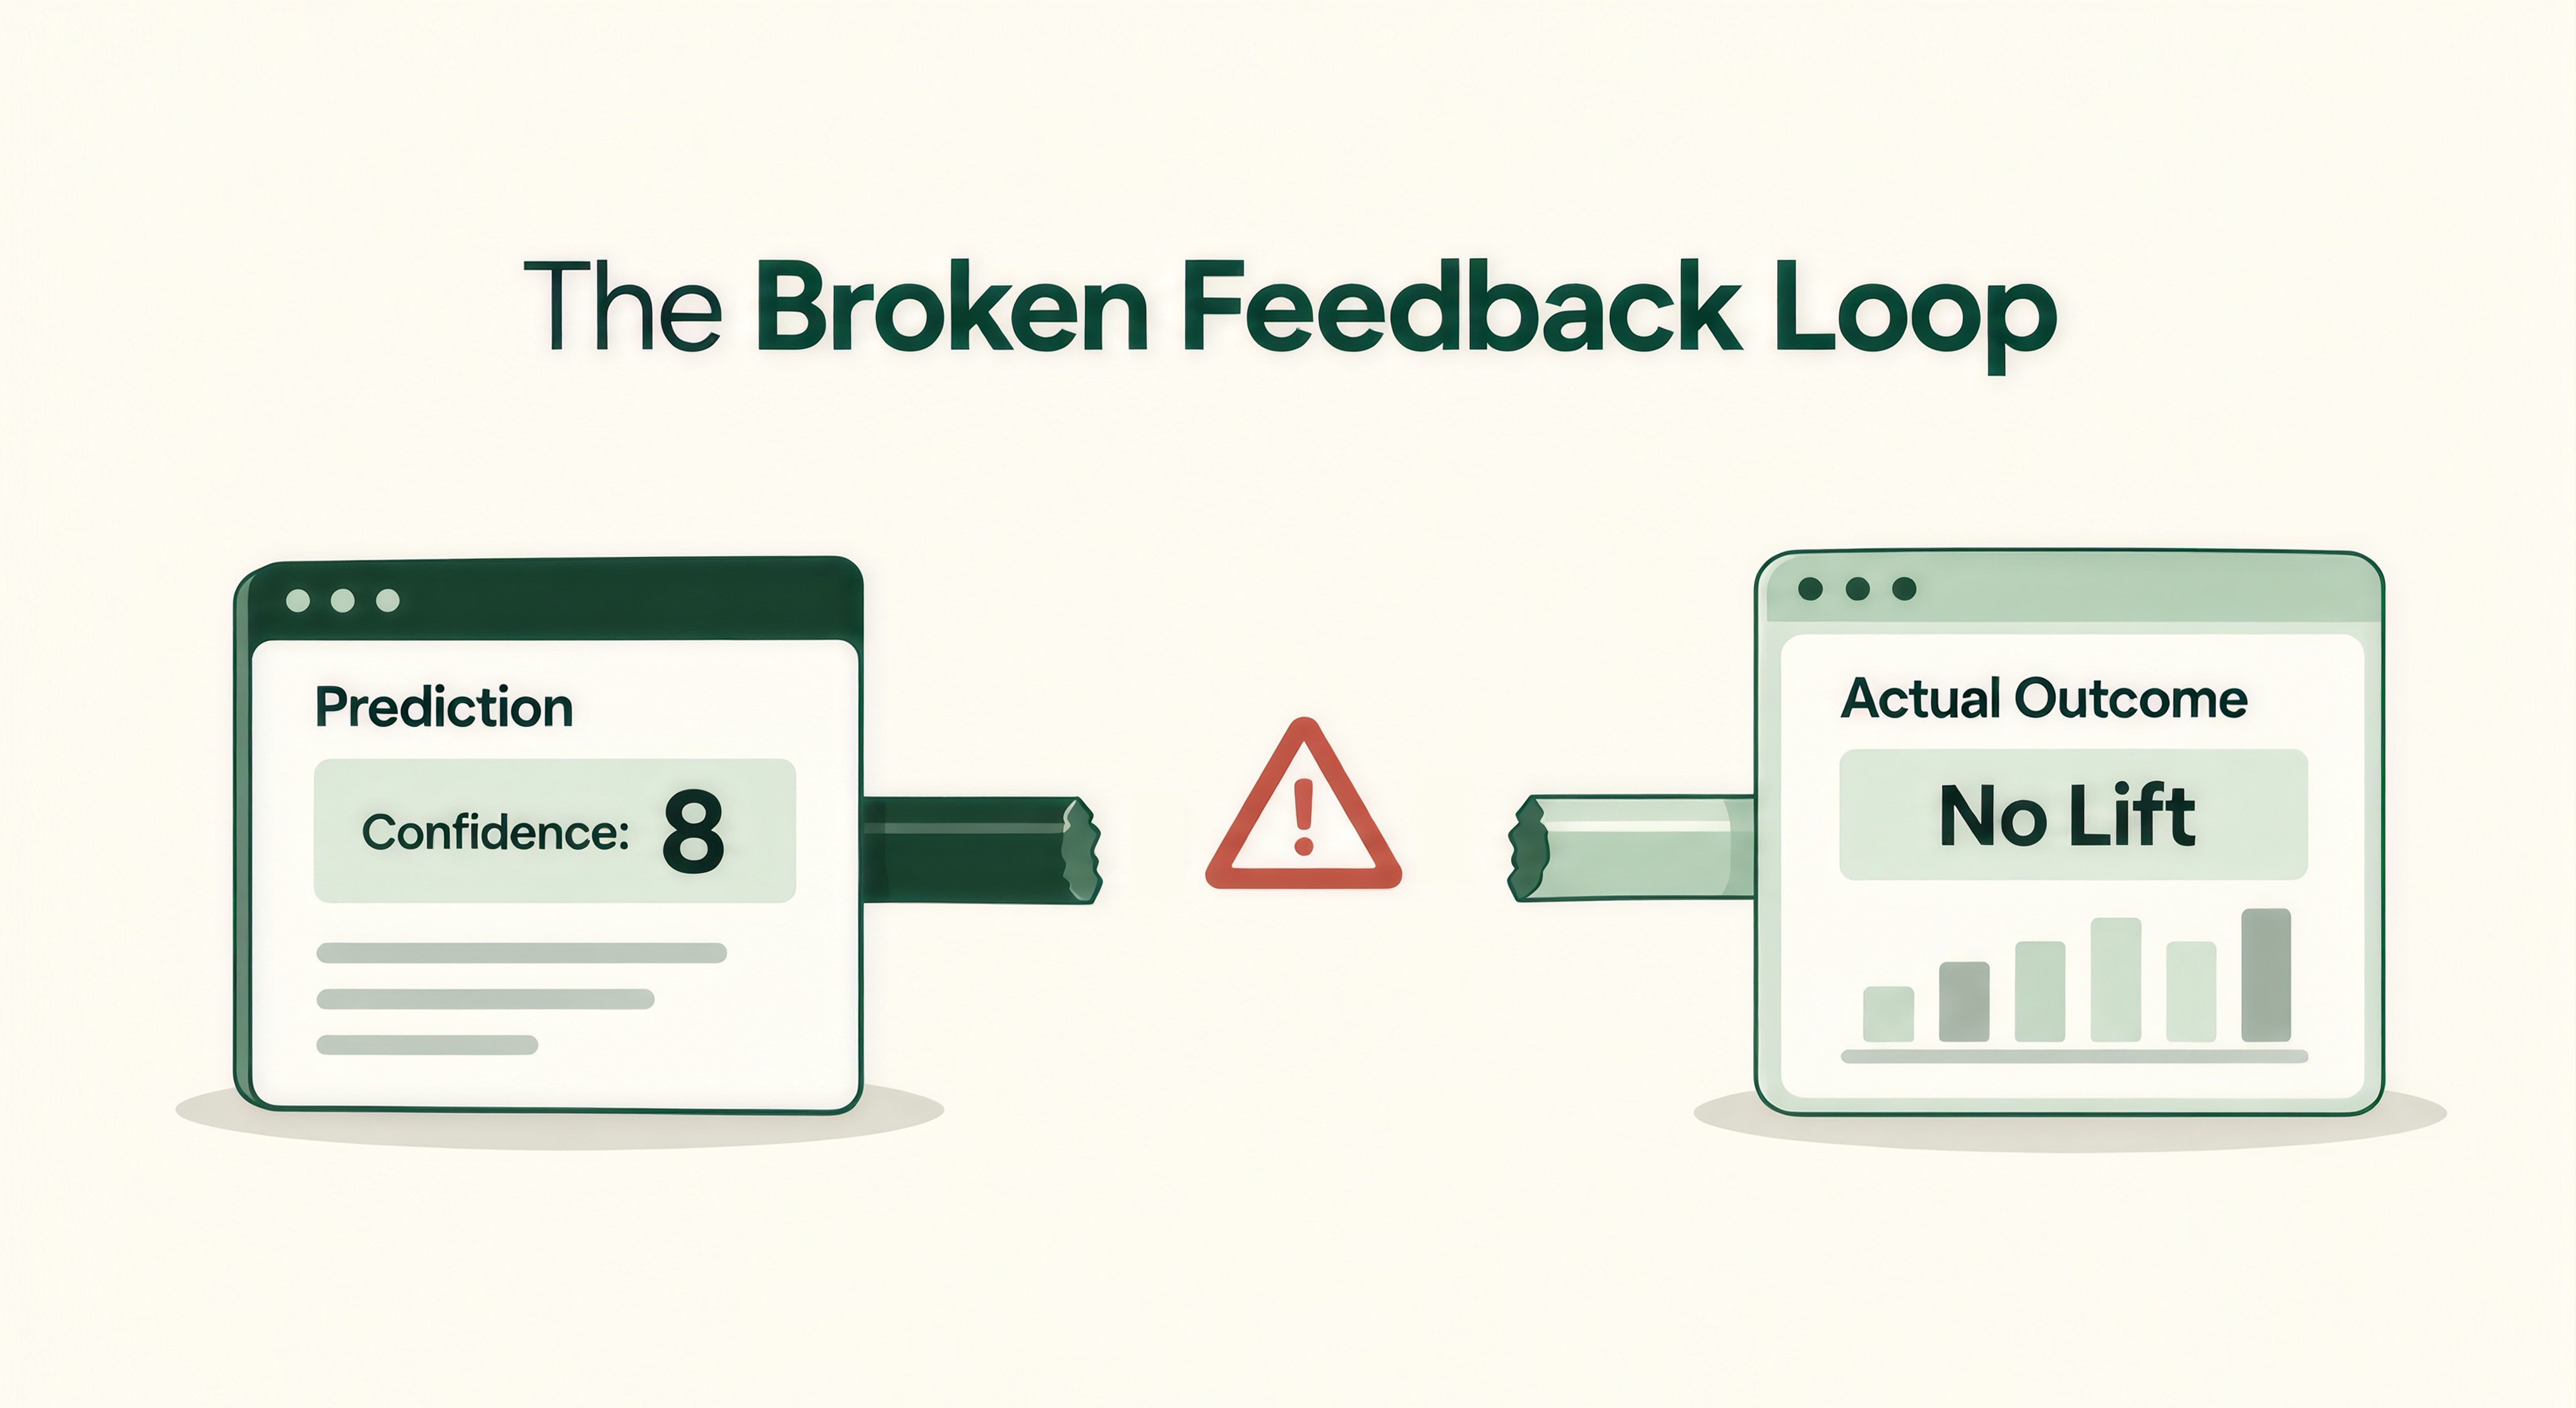
That’s a real gap, not just an academic one. Take a finding related to checking whether the sample split held up during a test. If that category keeps getting more confidence than it deserves, the blind spot just resets itself every quarter. Nothing about the process learns from being wrong.
None of this means ICE and PIE are worthless. They’re still better than no structure at all. Two changes make them meaningfully more honest without replacing them.
The first is scoring independently before anyone talks about it as a group. Kahneman’s research found that seeing someone else’s number first quietly pulls your own estimate toward it. Group discussion ends up hiding disagreement instead of surfacing it. Have each person score privately first, then compare. The gap itself is useful information.
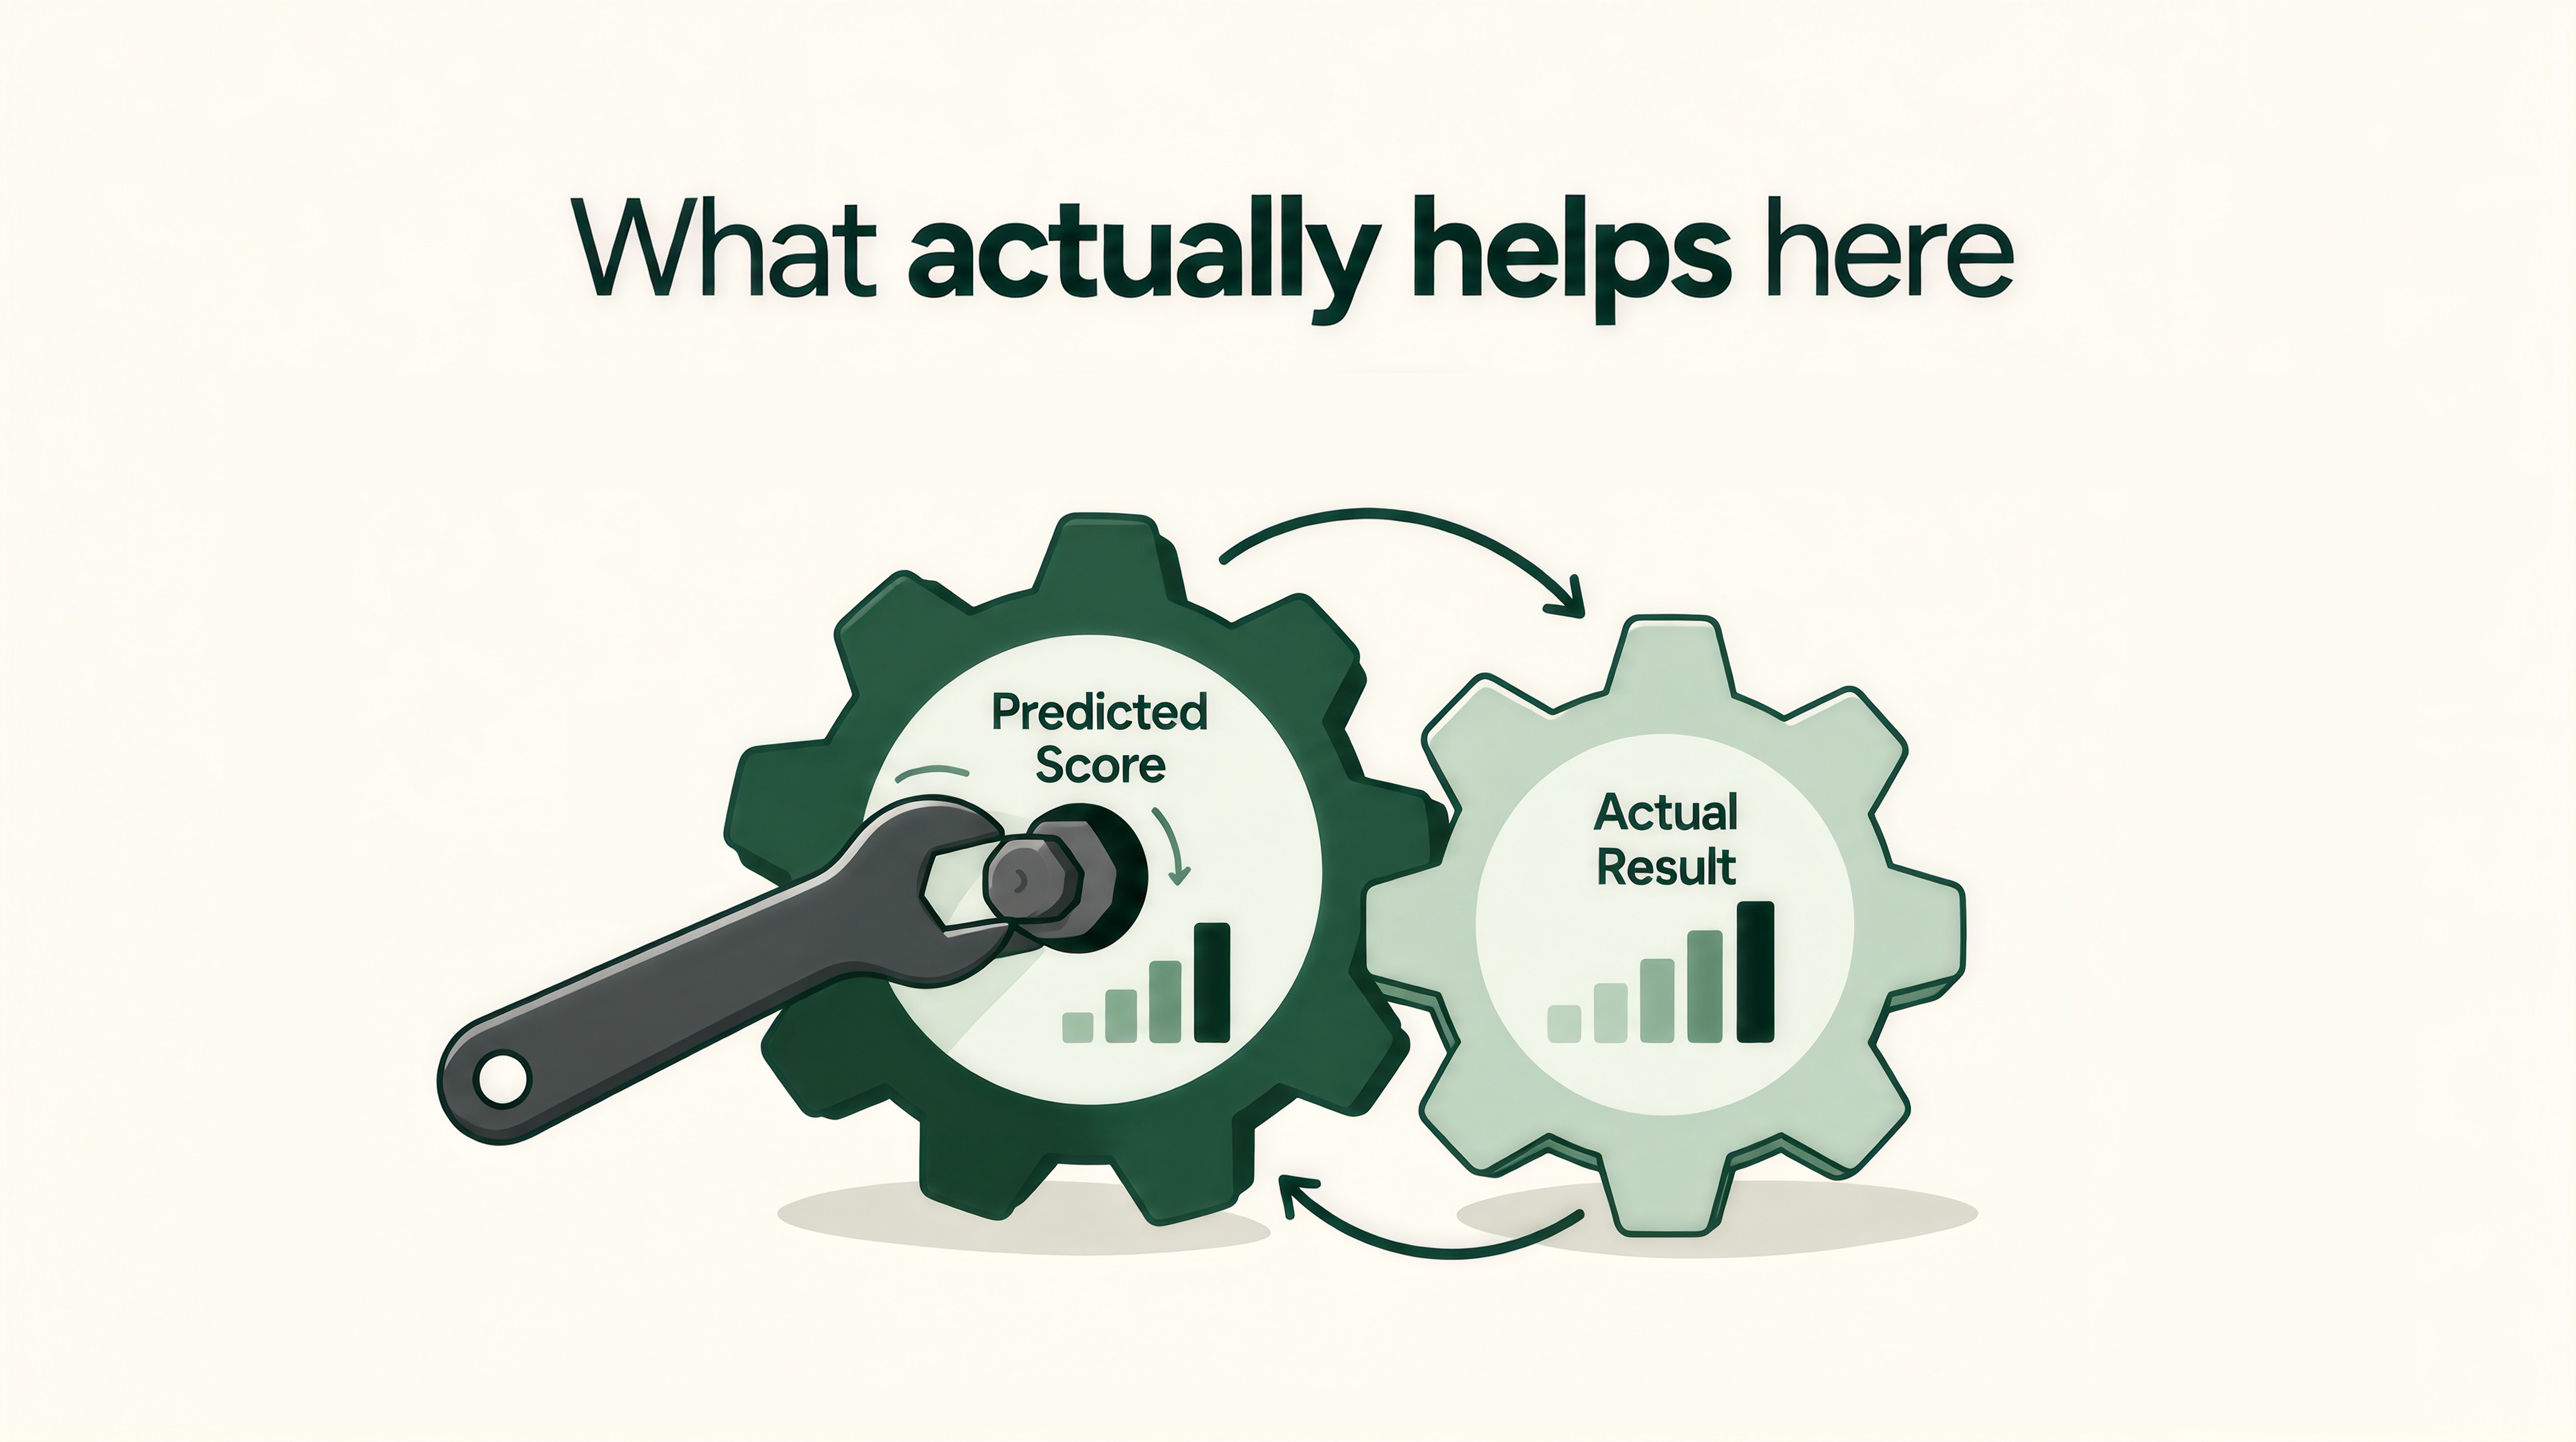
The second is going back and checking. When a test finishes, look at what the team predicted against what actually happened. Over time, that tells you which team member’s Confidence scores tend to run high. It also shows which categories of finding the team consistently overrates, and where the framework needs recalibrating rather than blind trust. It’s the same instinct behind treating the build process itself as something with real checkpoints, rather than a single pass you do once and move on from. A prioritization score deserves the same scrutiny a test result does, not less.

None of this is really about the formula. A funnel audit already tells you where the friction actually is. The scoring step is where teams start treating opinion as evidence without meaning to. Fixing that isn’t about finding a better acronym. It’s about being honest with yourself about which numbers in your spreadsheet are measurements, and which ones are just feelings that learned to count.
OptiPhoenix scores audit findings the same way we score test results, independently first, checked against outcomes later. Talk to our team about your audit backlog.
No, they’re still worth using. The problem isn’t the framework, it’s treating the numbers as more objective than they are. Score independently before group discussion and the framework gets more honest without changing at all.
It’s the most subjective of the usual inputs. Impact and Ease can often be tied to something concrete, traffic volume, dev hours. Confidence is closer to a gut feeling about whether an idea will work. That’s exactly the kind of judgment Kahneman’s research found varies wildly between people looking at the same information.
Try it once. Have two or three people score the same set of findings independently, without discussing them first, then compare. A wide spread on the same findings means the framework has been hiding disagreement rather than resolving it.
After a test finishes, look back at what the team predicted for Confidence or Impact and compare it to what actually happened. Done consistently, this shows which kinds of findings tend to get overrated and helps recalibrate future scoring instead of repeating the same miss.
Yes. Both frameworks multiply subjective inputs together and both have the same blind spot. The specific labels change, but the underlying problem, unverified confidence treated as data, doesn’t.